Expertise Discovery Assistant
Outcome
Let the staffing manager find the right consultant for a role by reasoning over verified skills, delivered project evidence, certifications and real availability rather than self-reported profiles, while respecting rate bands, location constraints and development goals.
| Portfolio attribute | Value |
|---|---|
| Primary persona | Staffing manager |
| Primary aggregate | ConsultantCapabilityProfile |
| Cosmos DB containers | 1 |
| Grounding data | skills, CVs, projects, availability, knowledge assets |
| Development estimate | USD 60-220 monthly dev estimate |
| Runtime options | Python FastAPI and C# ASP.NET Core |
Productivity hypothesis
These measures reflect the workflow, evidence, decision boundary, and industry risk for this use case.
| Impact type | Measure | Conservative internal assumption | Customer measurement |
|---|---|---|---|
| Productivity | Expert discovery time | 20-30% reduction | (baseline median expert-search minutes - assisted median expert-search minutes) / baseline median expert-search minutes * 100 |
| Quality or risk | Accepted staffing recommendations | 5-10 percentage-point improvement | assisted percentage of staffing recommendations accepted - baseline percentage |
Important: Conservative internal pilot assumptions only; not public benchmarks, commitments, or expected customer results. Validate against a comparable baseline or matched control cohort with mandatory human review.
Rationale: Search and ranking across expertise records can materially reduce staffing discovery effort.
Pilot guardrail: Validate skills, CV, project, location, and availability freshness; managers retain staffing authority.
Customer validation plan
- Baseline the current workflow with representative users and tasks.
- Run the accelerator on the same task mix with human review retained.
- Measure expert discovery time and accepted staffing recommendations with the documented formulas.
- Replace internal assumptions with customer-observed results before a business case.
Why Azure Cosmos DB
This AI solution needs an operational data plane, not only a vector index:
- Hybrid vector and full-text retrieval combines semantic recall with exact identifiers, codes, names, and domain language.
- Hierarchical partition keys and metadata predicates keep tenant and domain boundaries in the normal query path.
- Operational JSON, source chunks, workflow and agent state, feedback, and audit records remain together for low-latency reads and governed writes.
- Change feed reacts to source and operational updates without polling.
- Autoscale throughput, configurable consistency, and multi-region distribution support variable demand and enterprise availability.
Domain workflow
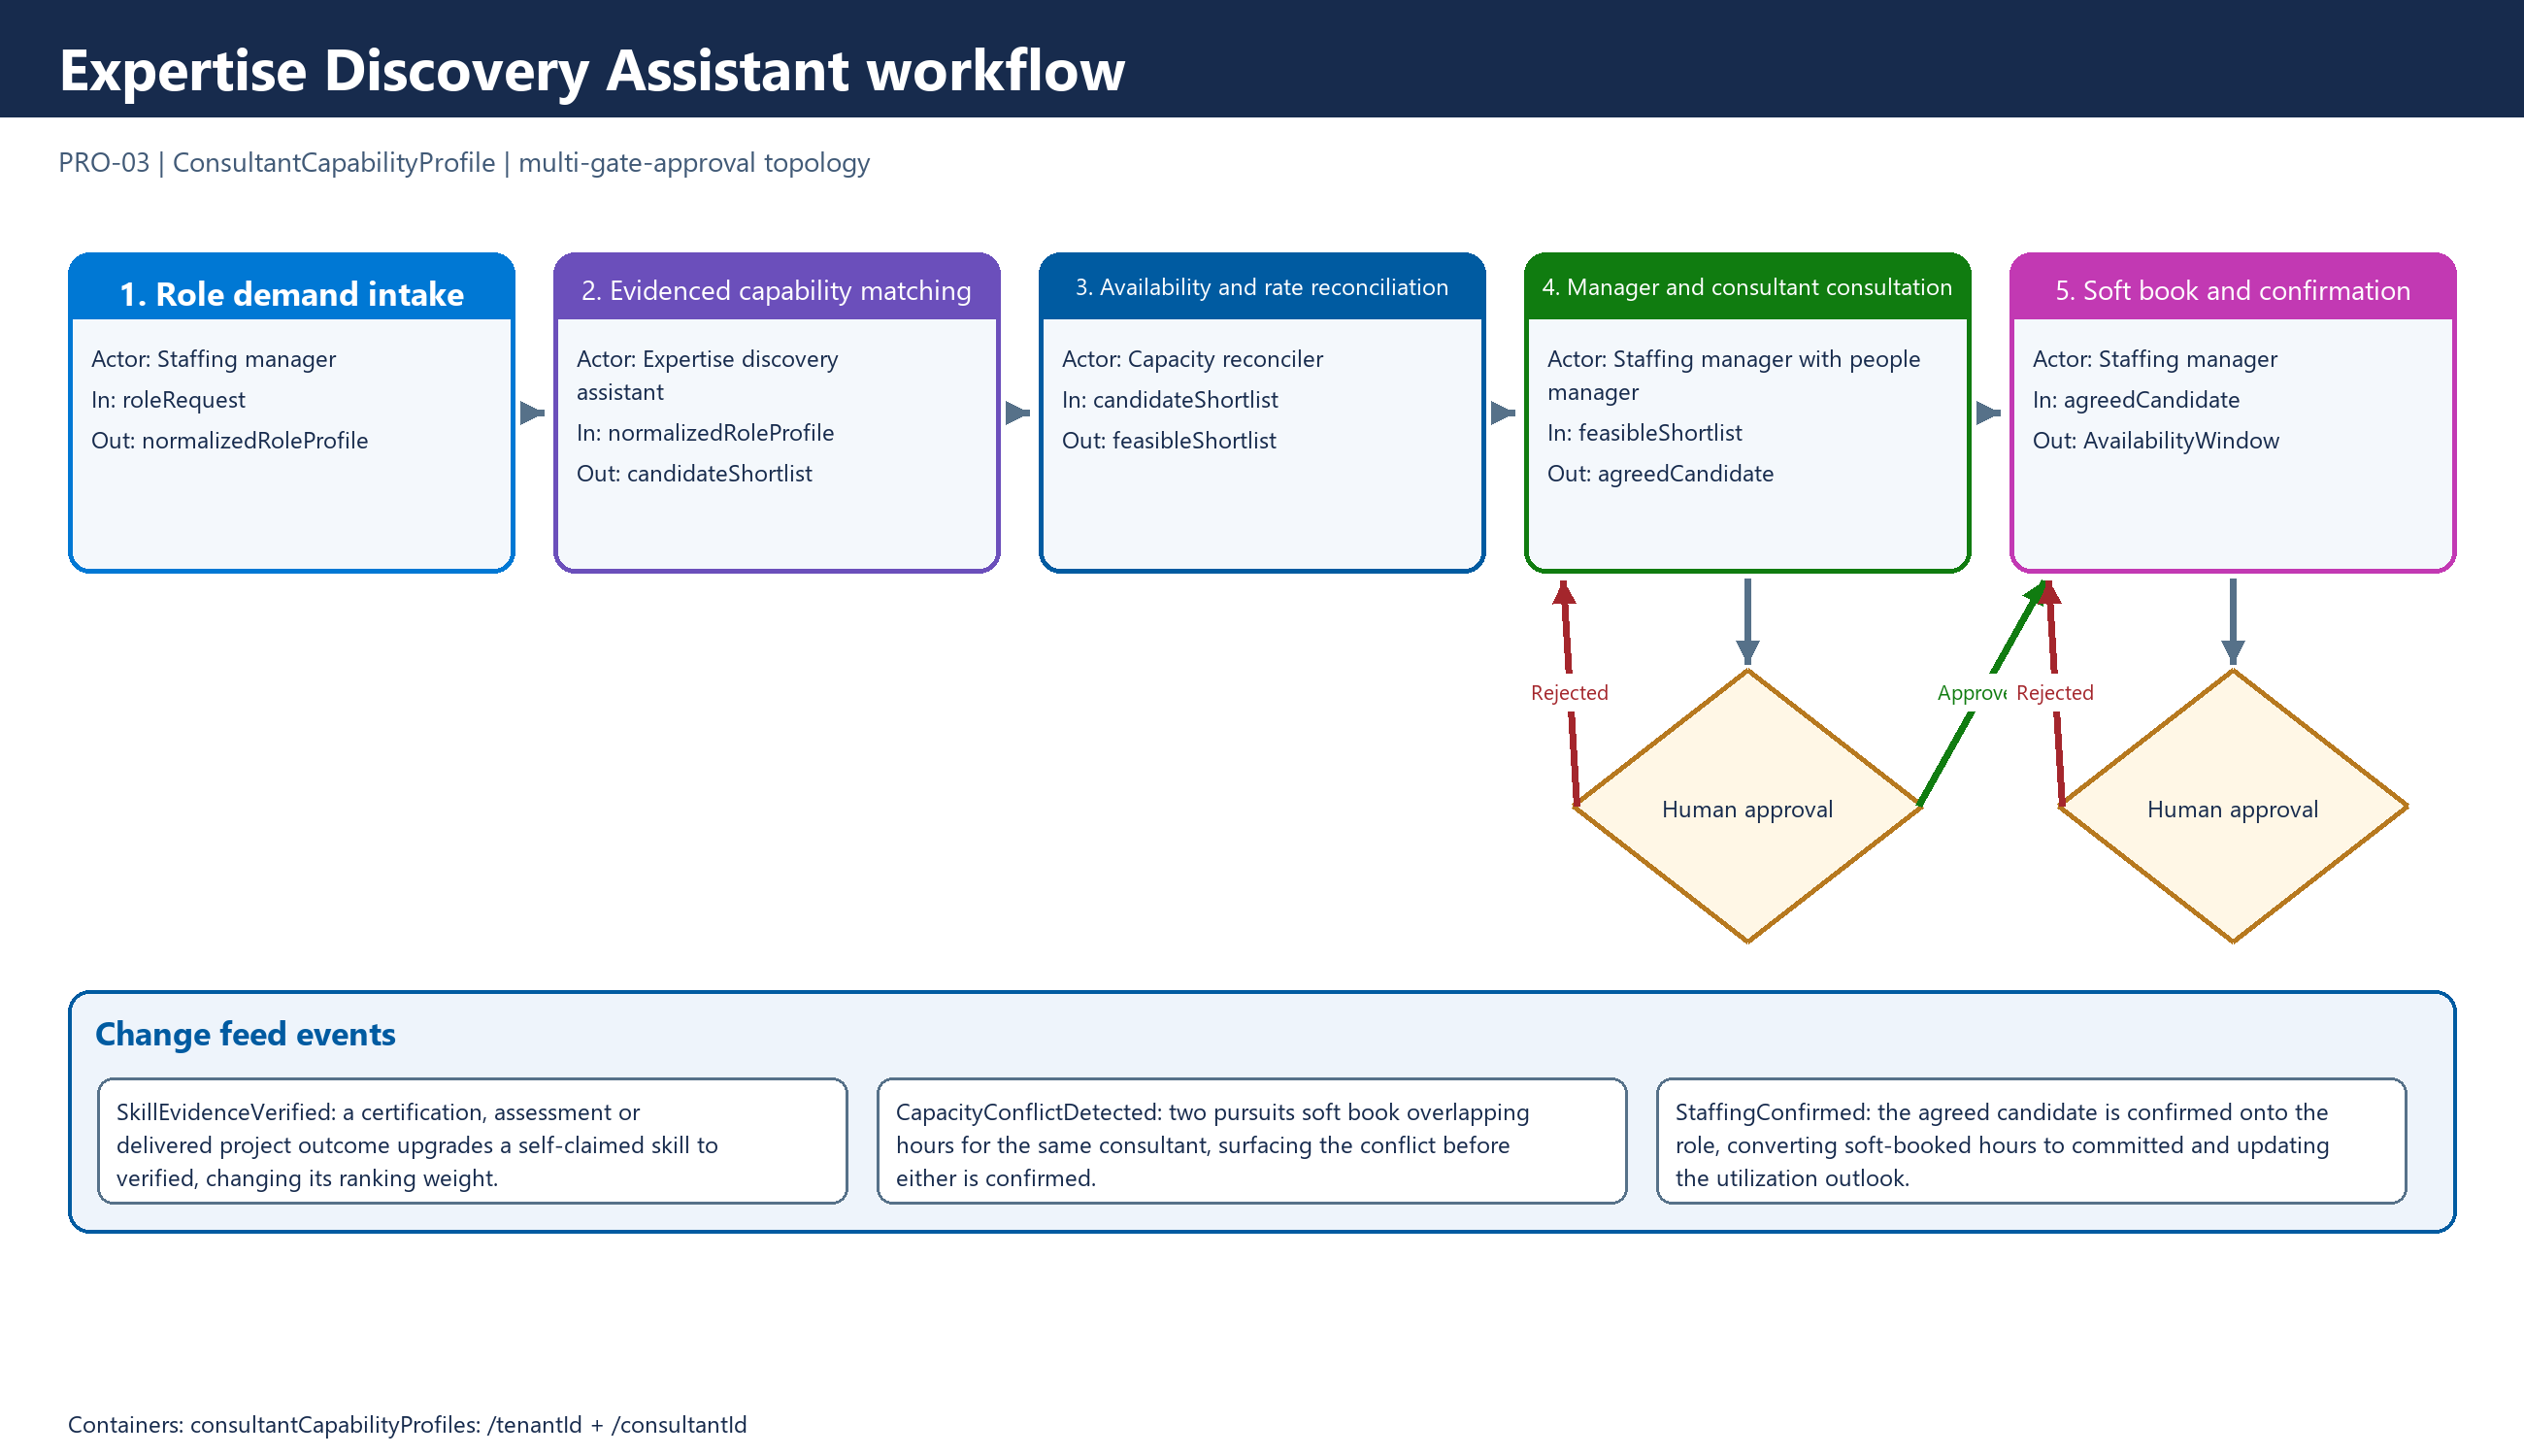
| Stage | Actor | Input → output | Approval |
|---|---|---|---|
| 1. Role demand intake | Staffing manager | roleRequest → normalizedRoleProfile | Policy controlled |
| 2. Evidenced capability matching | Expertise discovery assistant | normalizedRoleProfile → candidateShortlist | Policy controlled |
| 3. Availability and rate reconciliation | Capacity reconciler | candidateShortlist → feasibleShortlist | Policy controlled |
| 4. Manager and consultant consultation | Staffing manager with people manager | feasibleShortlist → agreedCandidate | Human required |
| 5. Soft book and confirmation | Staffing manager | agreedCandidate → AvailabilityWindow | Human required |
Technical architecture
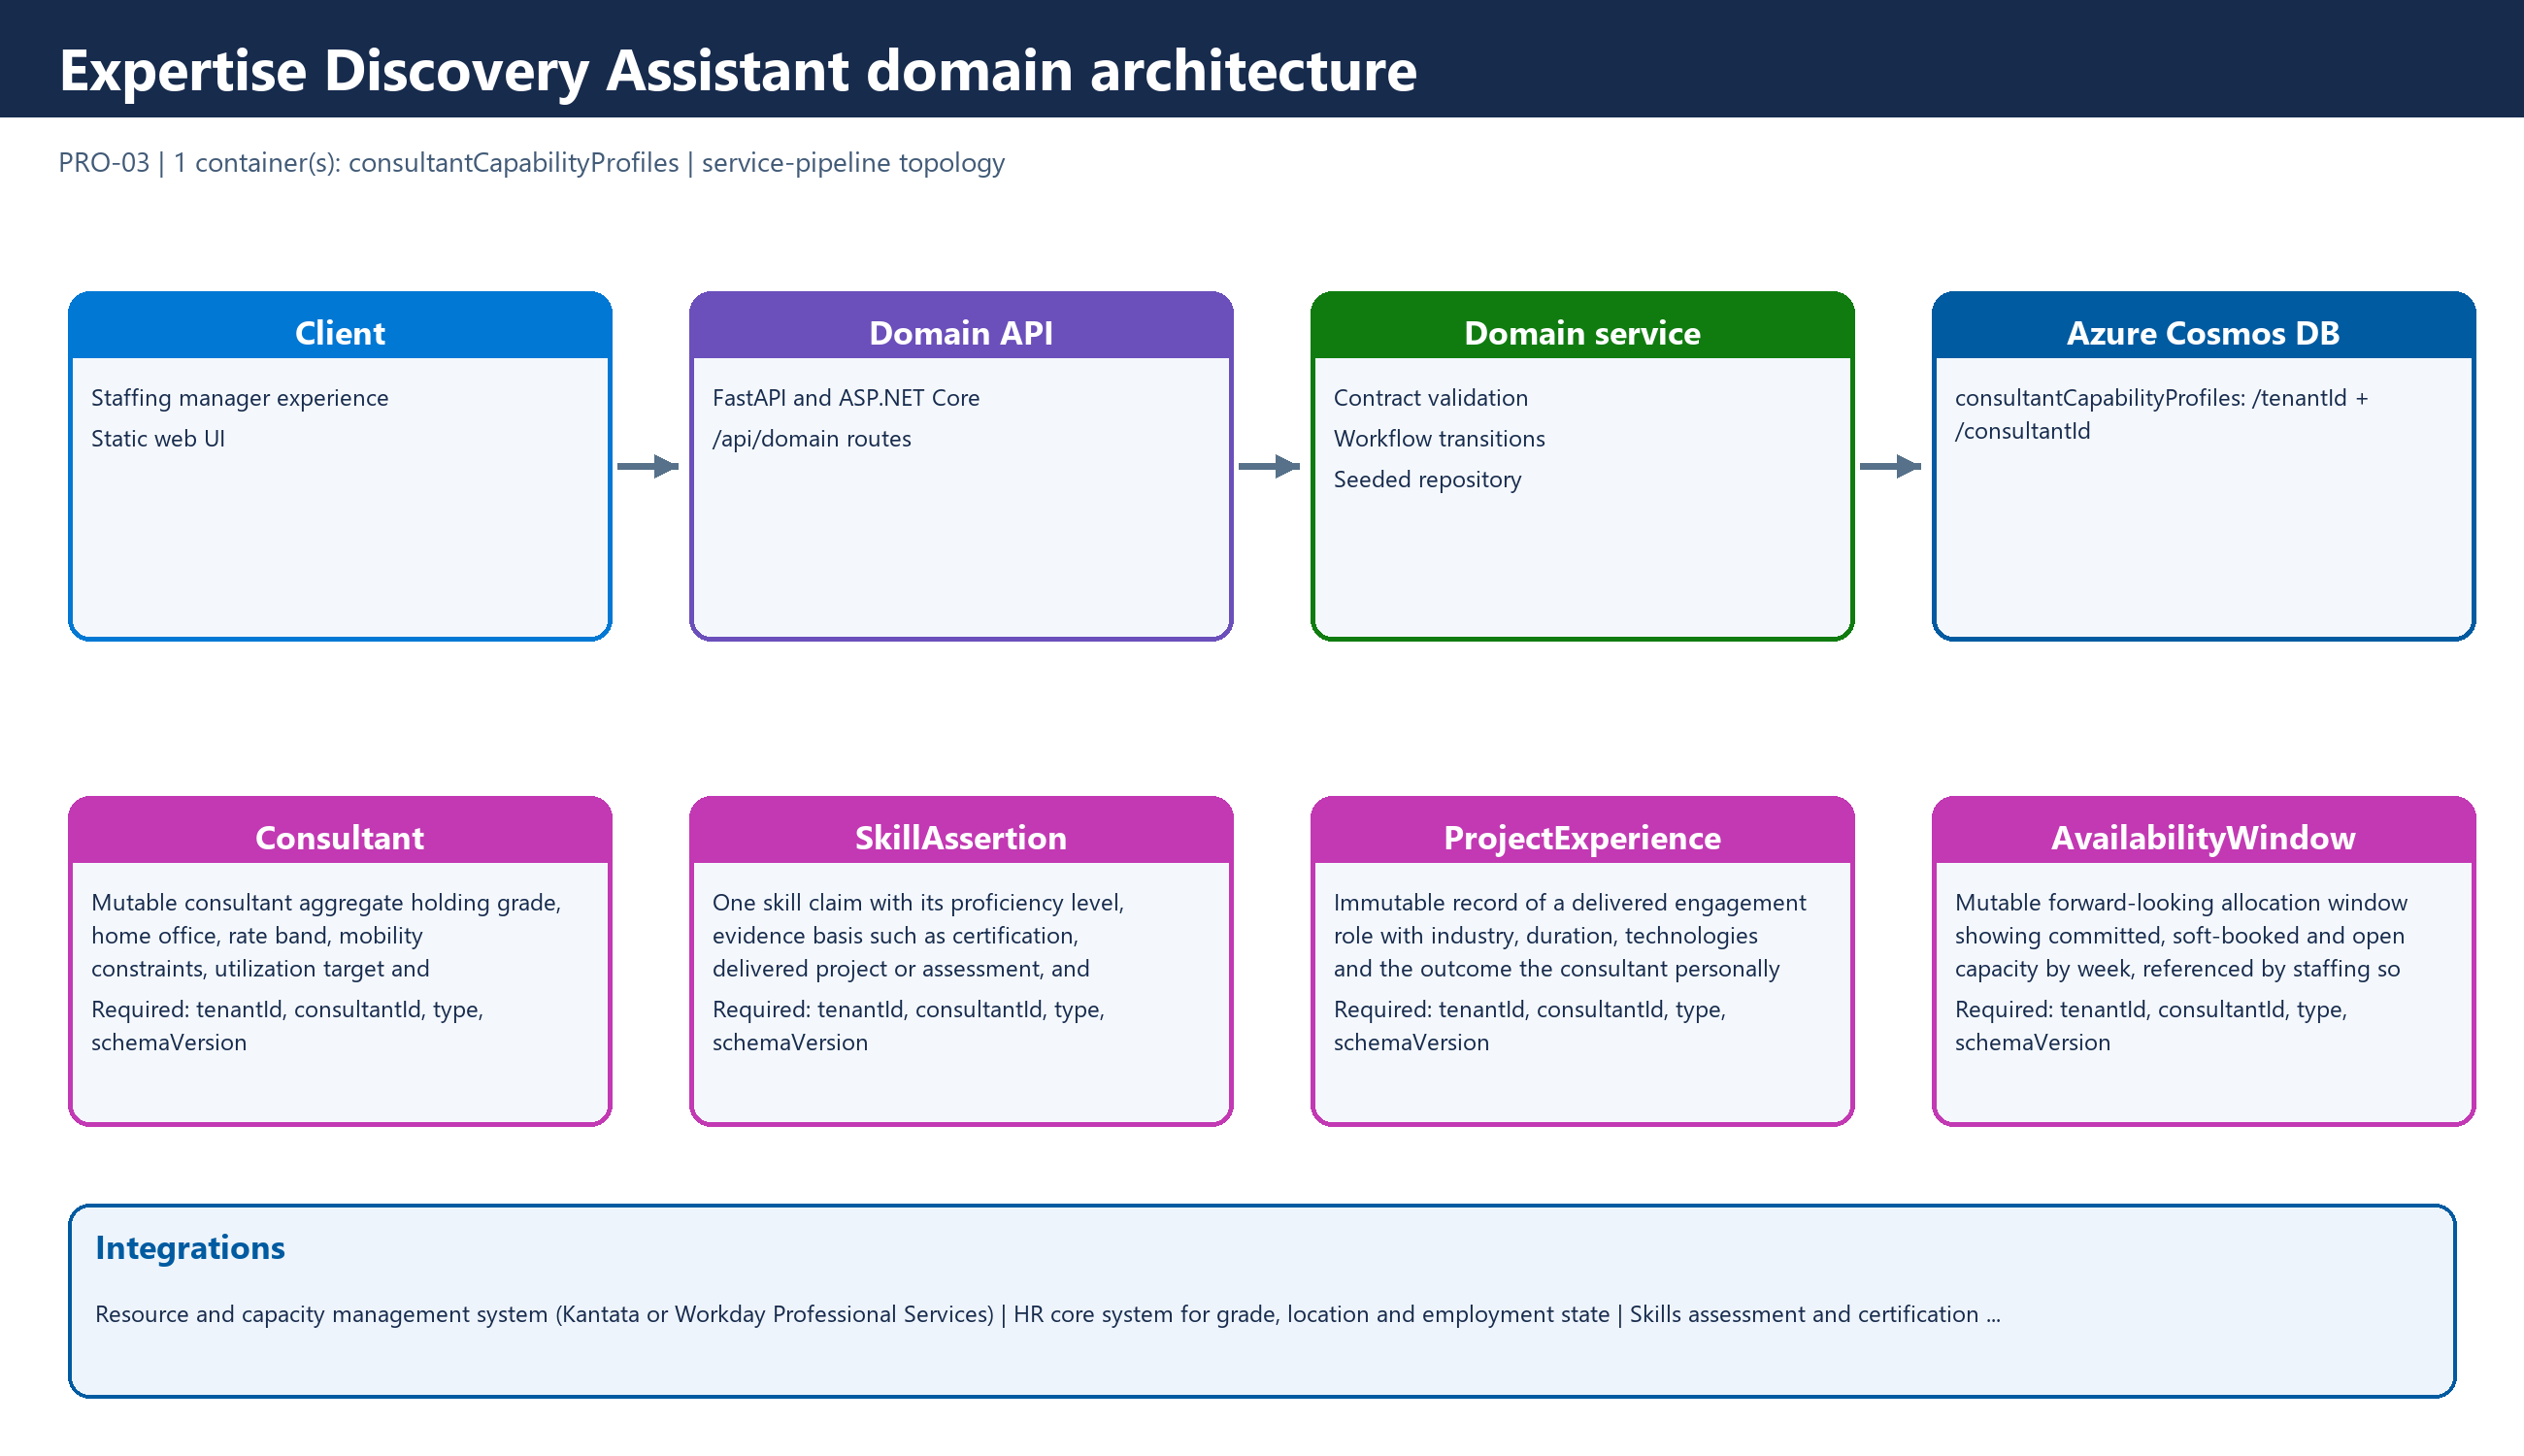
Cosmos DB data model
| Container | Hierarchical partition key | Documents | Search paths |
|---|---|---|---|
consultantCapabilityProfiles | /tenantId, /consultantId | Consultant, SkillAssertion, ProjectExperience, AvailabilityWindow, KnowledgeContribution, StaffingRecommendation | /experienceVectorEmbedding, /chunkVectorEmbedding, /experienceVector, /chunkVector |
Query contract
| Query | Container | Scope | Purpose |
|---|---|---|---|
| VerifiedSkillCandidates | consultantCapabilityProfiles | cross-partition-bounded | Find consultants with verified, recently used proficiency in the skills the role demands. Intentional cross-partition talent discovery: finding people the requester cannot name is the purpose, so the scan is bounded by the tenantId prefix, the required skill codes, verified assertions and a recency cutoff. |
| OpenCapacityInWindow | consultantCapabilityProfiles | single-partition | Check genuine open hours across the engagement's staffing window to avoid double booking. |
| DeliveredExperienceSearch | consultantCapabilityProfiles | cross-partition-bounded | Find consultants whose delivered engagement outcomes, not just skill tags, match the role context. Intentional cross-partition experience search: bounded by the tenantId prefix, one client industry and a topK vector limit. |
| ThoughtLeadershipDepth | consultantCapabilityProfiles | cross-partition-bounded | Surface authored assets that evidence depth beyond the skills taxonomy for niche roles. Intentional cross-partition contribution search: bounded by the tenantId prefix, one topic tag and a topK vector limit. |
Python and C# services route each document type to its declared container and hierarchical partition key. ETag-based writes protect mutable aggregates, while append-only records and bounded cross-partition queries preserve scale.
Azure deployment
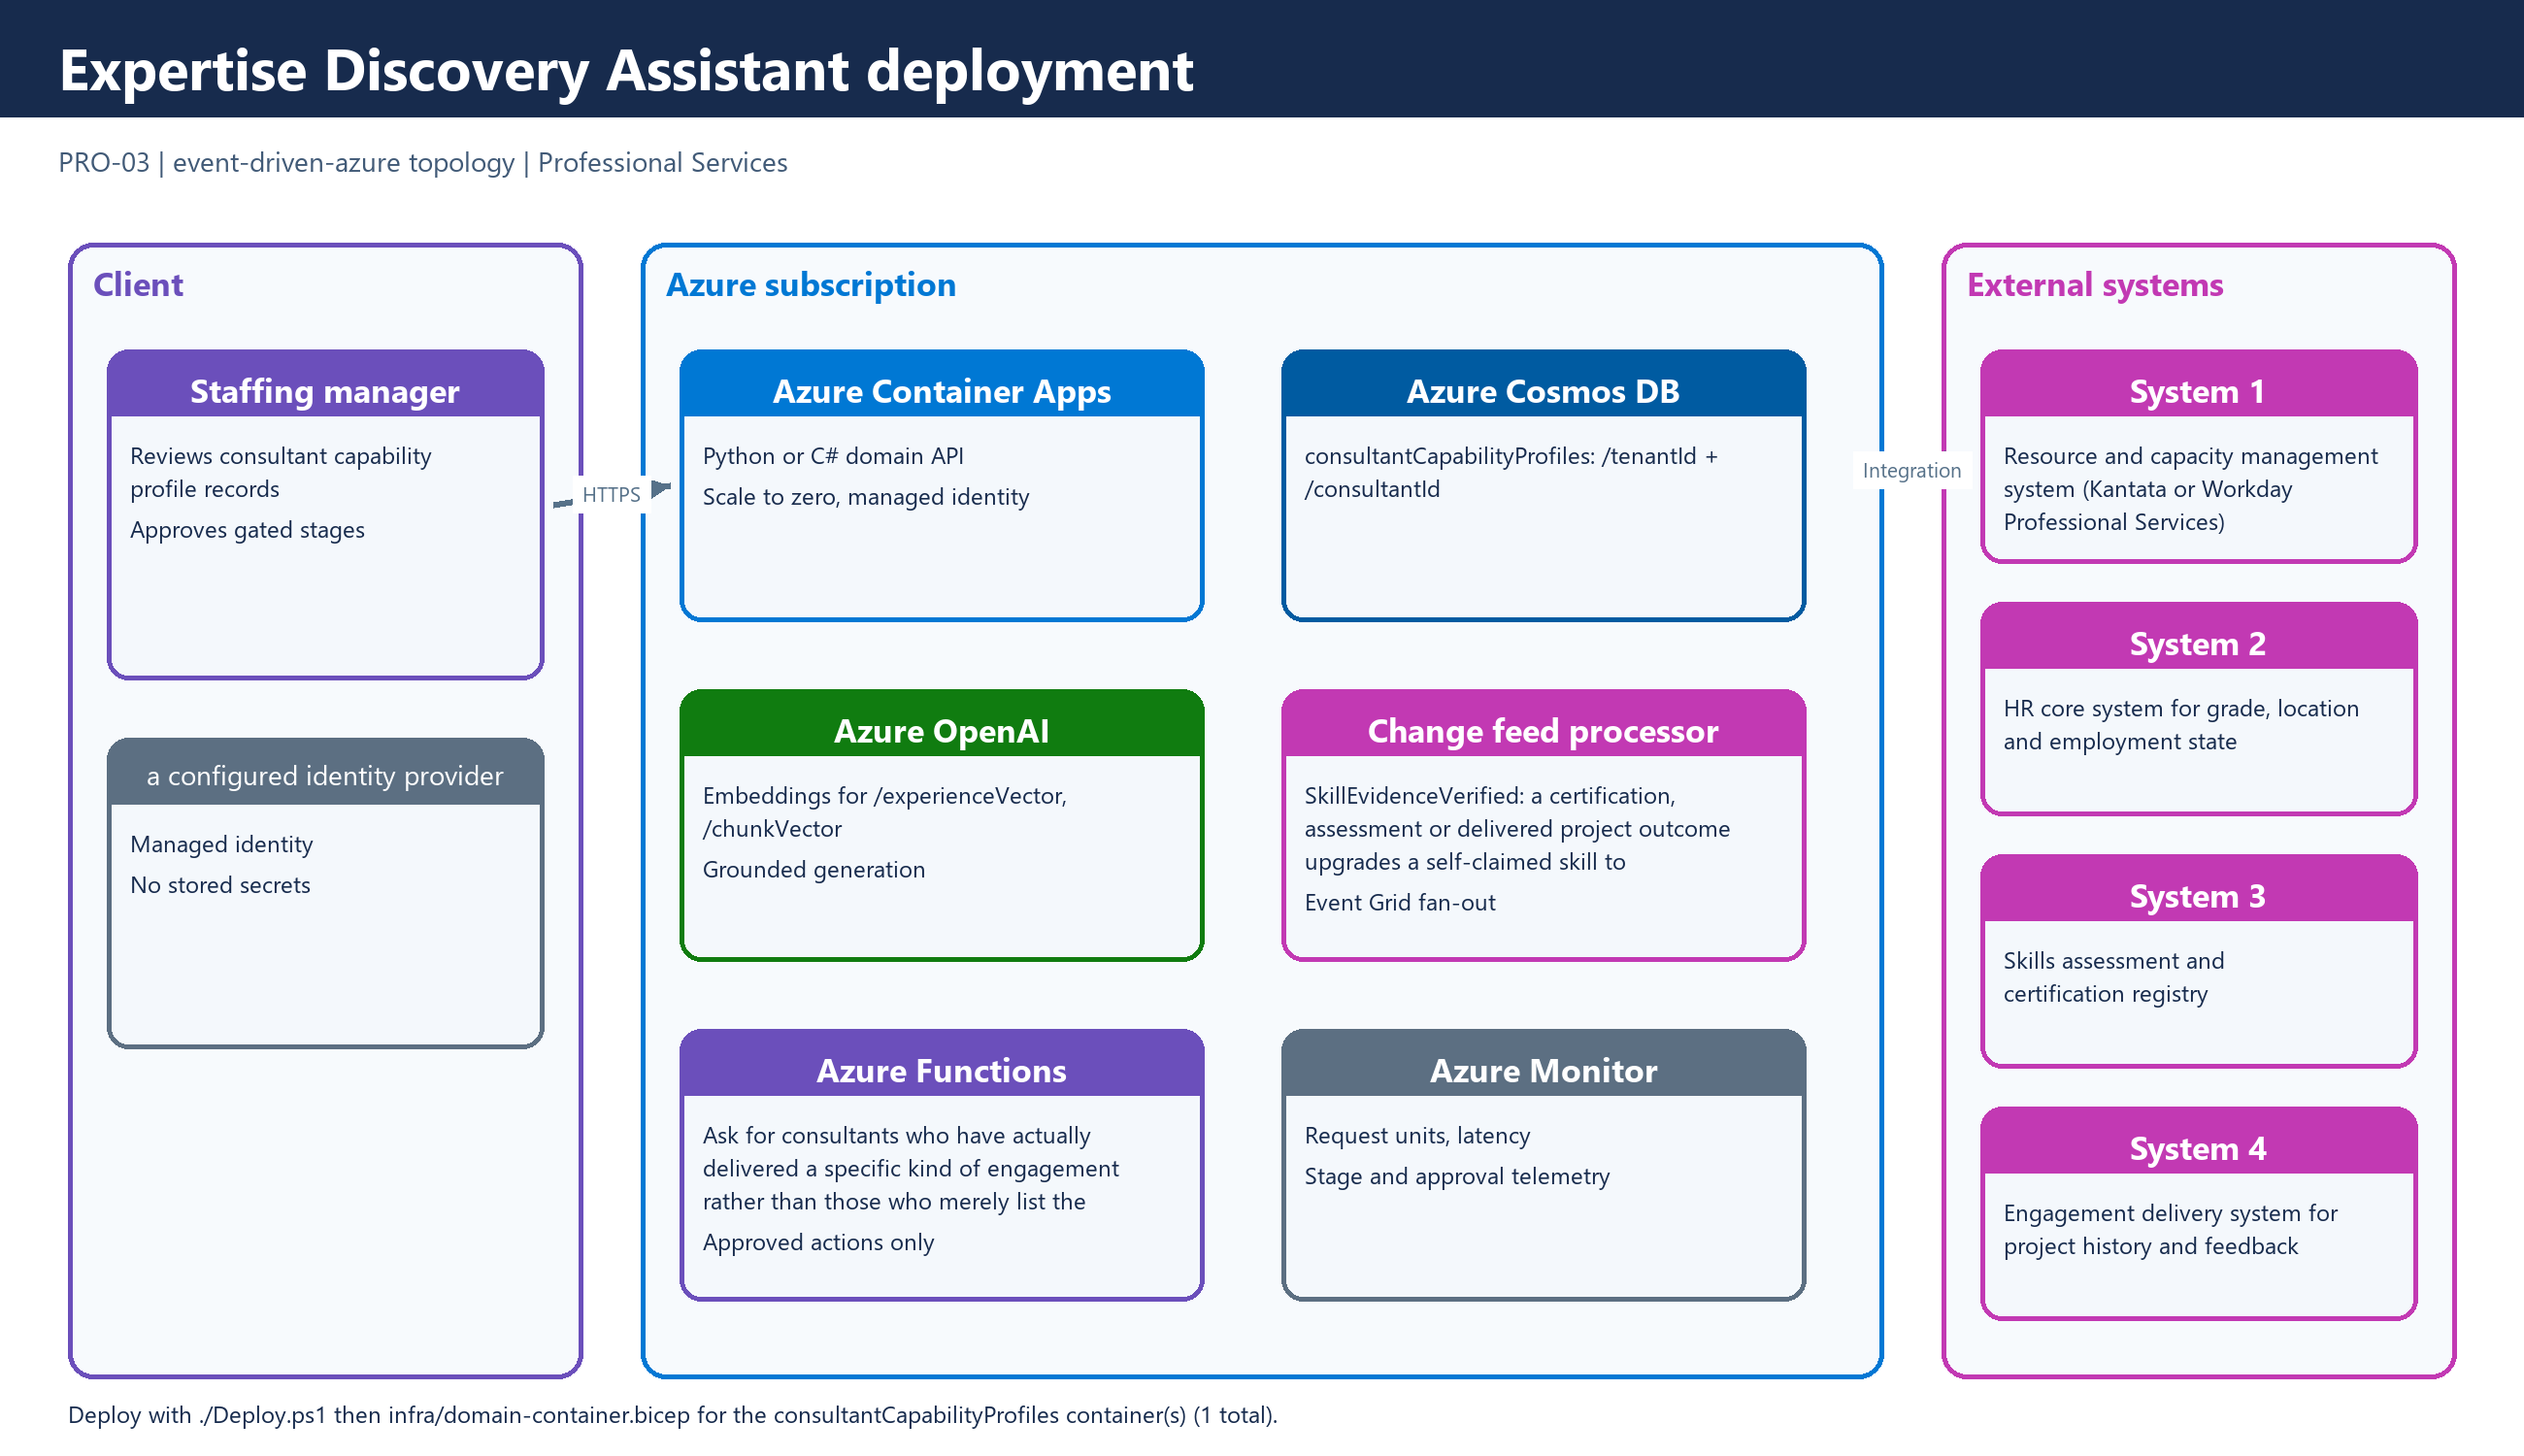
Clone the source repository, authenticate with Azure, and run:
Set-Location accelerators/professional-services/expertise-discovery-assistant
az login
./Deploy.ps1 -Runtime python -Location eastus2
Change python to csharp to deploy the .NET implementation.
Explore the implementation
- Launch signed-in demo
- Implementation article
- Domain data model
- Workflow and API contract
- Python application
- C# application
- Domain container Bicep
- Platform Bicep
- Cost and configuration
- Source repository